Webinar: The New Era of Agentic NetOps
Introducing Selector Foundry
Webinar: The New Era of Agentic NetOps
Introducing Selector Foundry

Agentic NetOps, delivered by a team of specialized agents. They investigate the incident, act inside your guardrails, and prove the fix, resolving incidents in minutes before your users notice.
Noise reduction
Faster RCA
Fewer incidents


Your tools each see one part of the path. Selector sees all of it, and now acts on it.
Selector Foundry runs a smart alert to a root cause: it investigates, coordinates specialists and recommends a fix, each at 02:40, then verifies recovery while flagging that the same push is staged on 2 more routers and waits for your approval.
Diagram: Selector’s agentic runtime. Rosetta calls five agents — Loom, TicketMaster, Artist, Herald and Sculptor — and the runtime connects to all four services: Collaboration, Knowledge, Data hypervisor and Collection. Raw telemetry, network, cloud and infrastructure, and existing tools and integrations all feed the Collection Service. In this example 1,412 signals across three alert clusters resolve into one episode on edge-rtr-3, with a device reboot as the root cause.
Connected to every service
Rosetta → Loom · Retrieve the related signals behind this incident.
Insight where you work.
Link failure → BGP session flap.
Teams · ServiceNow · PagerDuty · Jira
Device reboot→Link failure→BGP session flap
One shared identity.
Any source. Any cadence.
Correlation collapses the noise into a single incident, names the probable root cause and its blast radius, and recommends the fix, ready before anyone is notified and delivered where you already work.
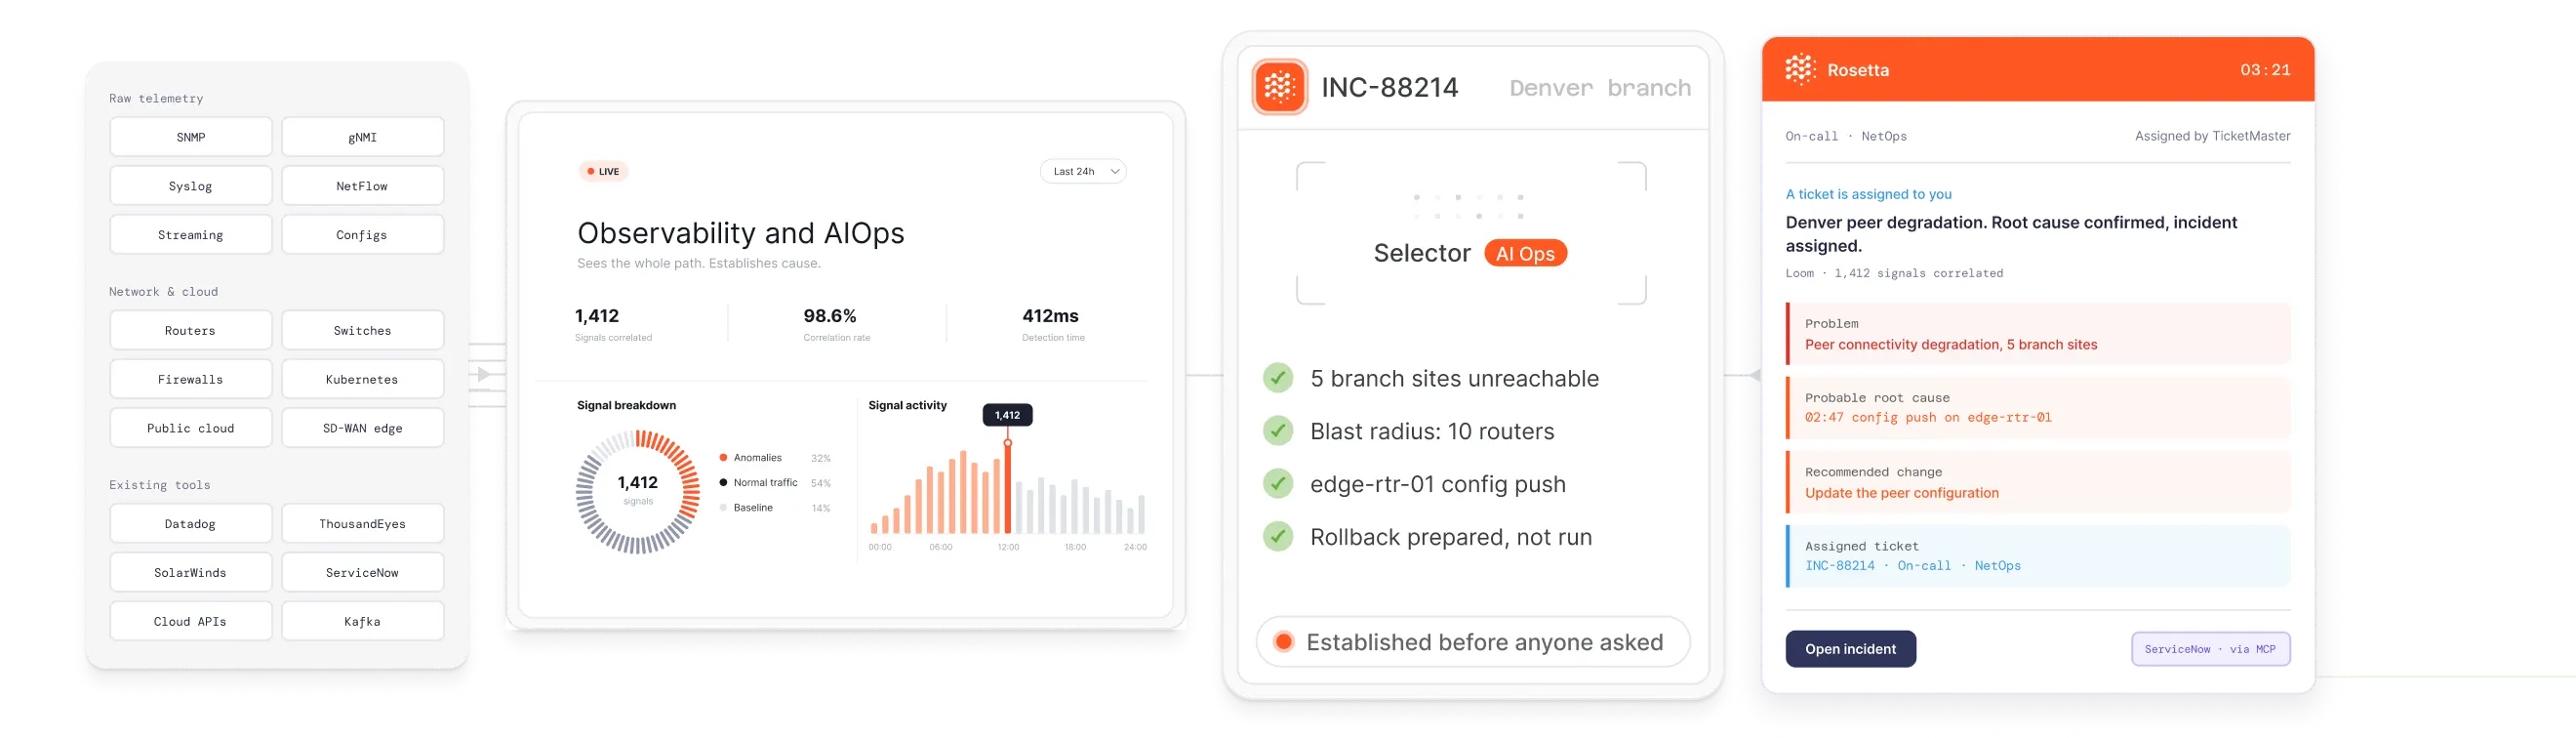
One shared context, a team of specialized agents.
Ask Rosetta in plain language and get the live state of your hybrid network in one place.
Product demo: in the Rosetta chat window, “Give me a report of my branch routers” is answered by the Physical Infrastructure agent. It makes three inventory calls — get_network_device_inventory twice and get_facility_opstate — and returns a Branch Routers Inventory Report: 35 branch routers monitored across 7 regional hubs (Seattle, Dallas, Chicago, New York City, Los Angeles, Miami and Denver), followed by a summary table of region, site, device name and IP address.
Selector watches continuously and surfaces the signals that matter, with the context to know why.
Product demo: in the Rosetta chat window, the question “are any of these unhealthy?” is answered with a synthetics health and reachability check across the branch routers. Most are healthy and reachable; all 5 branch routers in the Denver region are currently unreachable — Albuquerque, Billings, Colorado Springs, Wichita and Salt Lake City. Branch routers in every other region are operating normally.
Product demo: in the Rosetta chat window, “show me the active incidents right now” returns the active incident list, then “deep dive the incident in ashburn” runs the Incident Analyzer on S2INC-EQ-ASH1-EDGE01. The investigation names the likely cause — a configuration change under change ticket CHG0048271, titled “Optimize BGP convergence and add monitoring”, which destabilized the control plane on EQ-ASH1-EDGE01 — then lists the 10 regional branch sites whose reachability it disrupted, the blast radius, the timeline, the evidence and six recommended remediations.
Product demo: in the Rosetta chat window, “Show me the offending lines in the config” returns the configuration changes made to EQ-ASH1-EDGE01 under change ticket CHG0048271 — five violations against the golden baseline: an hourly BGP-ROUTE-REFRESH EEM applet, BFD removed from all 10 branch interfaces, BGP timers shortened from 10 30 to 3 9, maximum-prefix limits cut from 1000 to 50, and graceful restart disabled — each shown as a configuration diff. A corrected file, EQ-ASH1-EDGE01_good_config.txt, is then attached to the second prompt, “I've fixed the config. Would this address all the issues above?”, and the analysis confirms all four checks pass and the control plane instability is resolved.
Product demo: in the Rosetta chat window, three turns. First, “I just uploaded the config...can you re-run the analysis and tell me if we're back in a compliant state.” confirms EQ-ASH1-EDGE01 is operationally remediated after CHG0048271 — the EEM applet removed, BFD restored, BGP timers, prefix limits and graceful restart back to baseline — with the only remaining discrepancy a configuration header timestamp. Second, a request to set up an event-based config agent that watches for config diffs and notifies the team on Slack returns the registered agents and a proposed configuration for confirmation. Third, “Yes, this looks good to me. Create it.” creates the agent config-compliance-watcher, now active and monitoring future configuration changes.
Selector agents run on your data, in your environment, on the LLM you choose. Yours to build, version, and govern.
Grounded in evidence
Every answer starts from correlated evidence. Click any claim to see the telemetry or config diff behind it.
Your data, your model
Agents run where your data already lives, so nothing goes to an outside service. You choose the LLM.
Built and versioned by your team
Author agents, commit them to your Git, and test against past incidents before promotion. Runs under your RBAC.
Product demo: in the Rosetta chat window, “deep dive the incident in ashburn” runs the Incident Analyzer on S2INC-EQ-ASH1-EDGE01, a P2 incident on the Equinix Ashburn hub router EQ-ASH1-EDGE01. The analysis walks its evidence: the incident overview, the root cause — a configuration change under change ticket CHG0048271 titled “Optimize BGP convergence and add monitoring” — five specific configuration regressions, the blast radius across 10 branch border routers, and a revert plan. Rosetta then answers with the likely cause and the ten regional branch sites whose reachability it disrupted.
Selector Foundry contains a set of specialized agents, each one an expert in one job with its own tools and guardrails. Ask in plain language, and the right agent takes it from there.
Selector correlates network, cloud, infrastructure, and application data into a single operational picture. Build the views your team works from, watch them update, and ask your dashboards what they show in plain English.
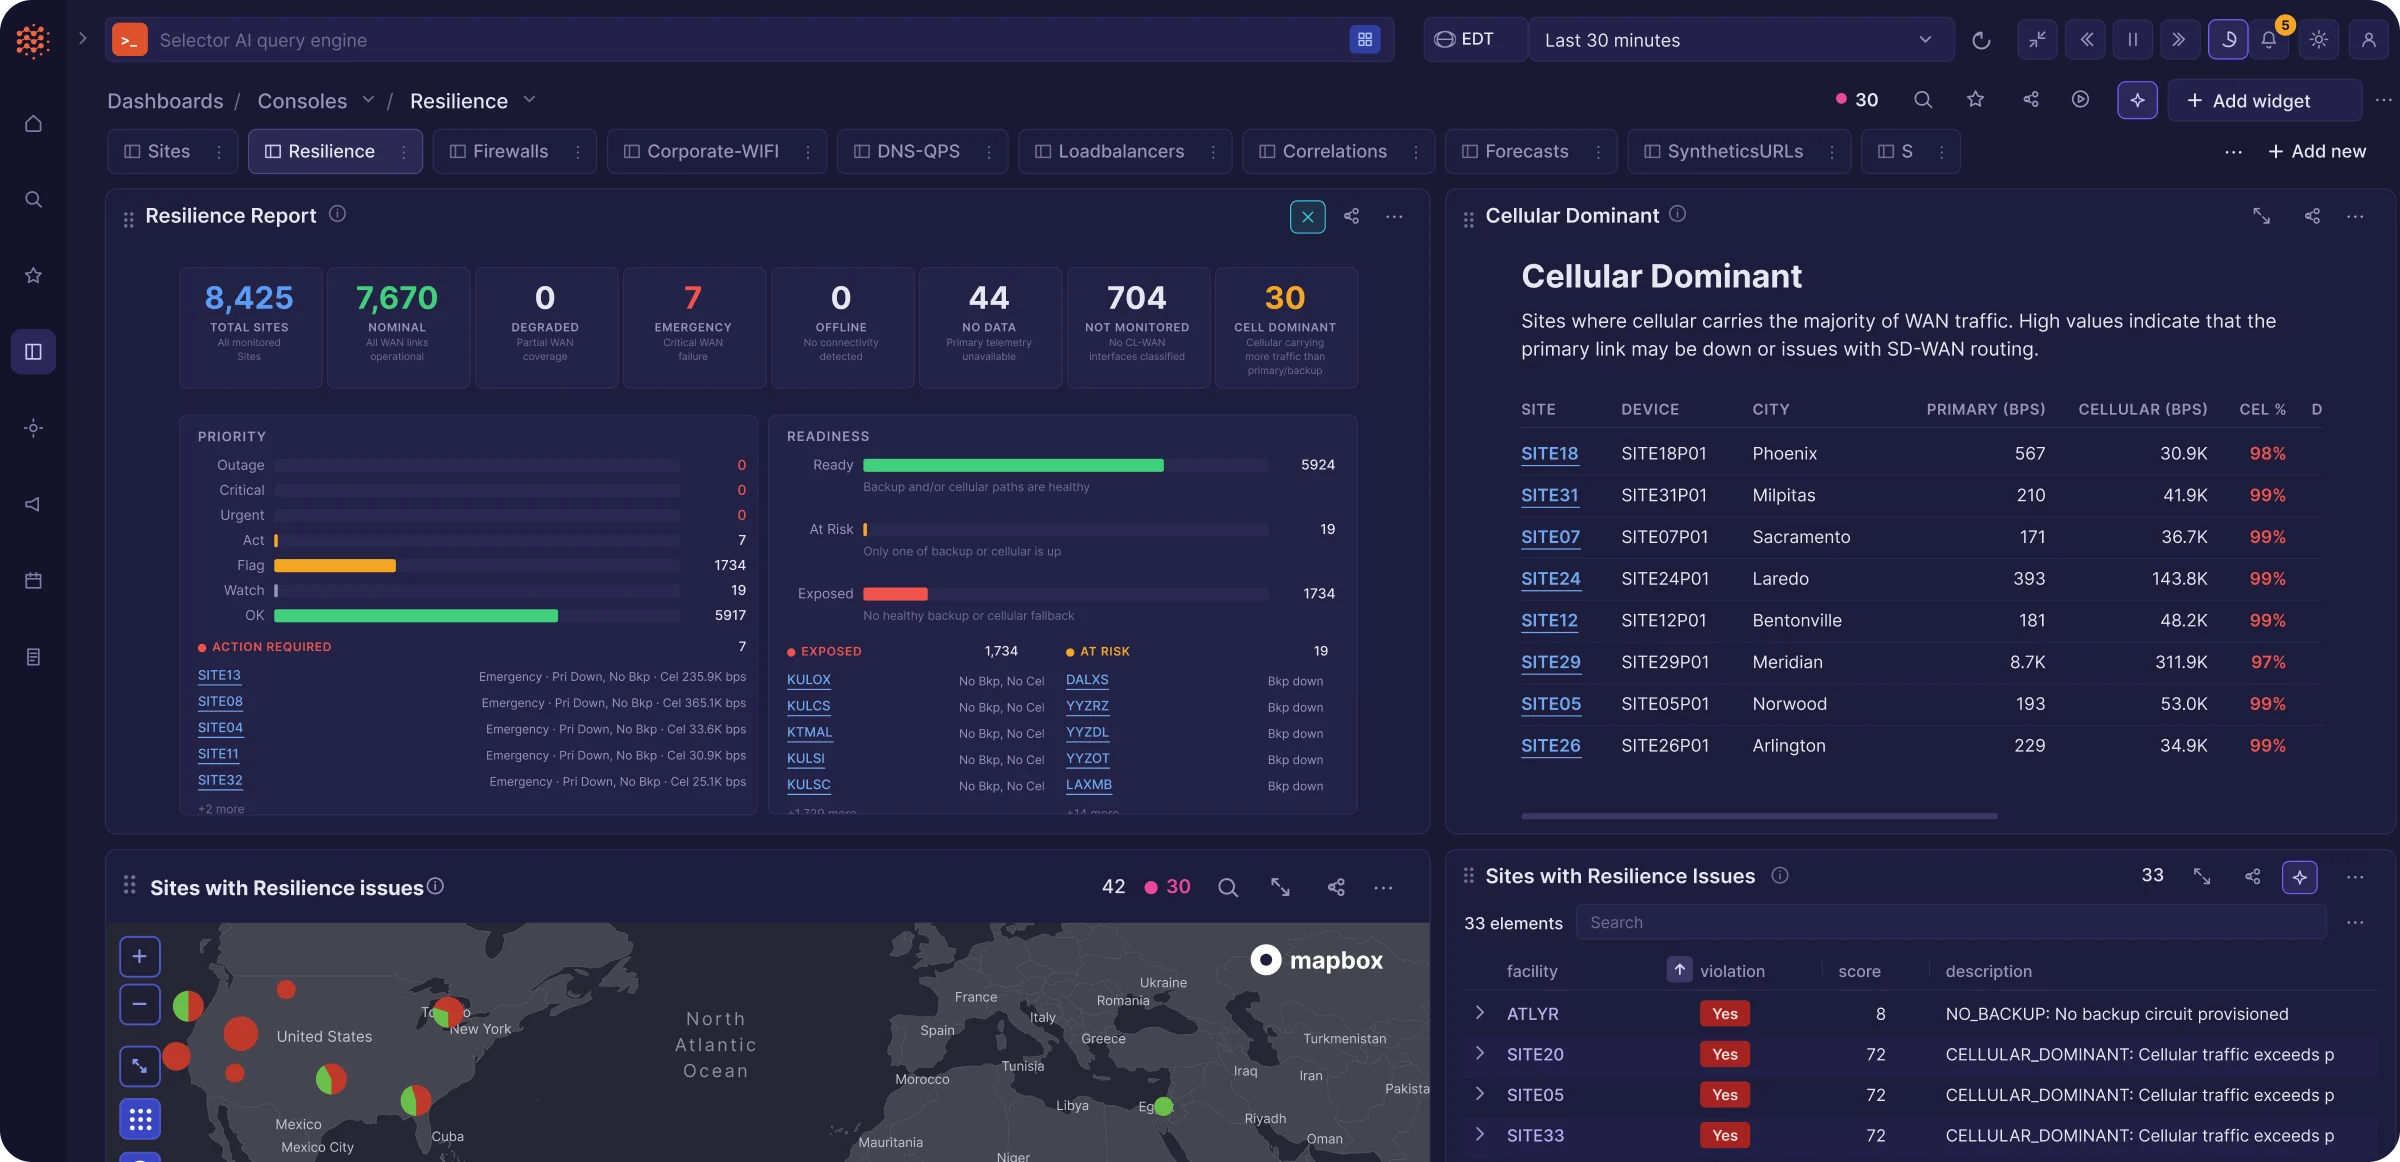
Network, cloud, infrastructure, and application data arrive already correlated, so one screen shows the whole operational picture.
Design consoles around how your team runs, from WAN resilience to firewalls, DNS, and synthetics, with no query language required.
Query any dashboard in natural language, and Selector returns a written summary of what it shows and what needs attention.
Read Gartners latest resport on Agentic NetOps Software to understand how the market is evolving, which capabilities matter most, and why Selector is recognized as a representative vendor in this emerging market.
Selector helps global enterprises reduce MTTR, unify visibility, and build resilient systems across every network domain.
A leading financial information and analytics company partnered with Selector to improve alert quality, unify telemetry sources, and strengthen operational visibility across complex environments.
A global data center provider deployed Selector to suppress alert storms, automate triage workflows, and reduce troubleshooting effort across large-scale infrastructure operations.
A leading financial services firm used Selector to unify multi-domain visibility across hybrid environments, helping teams reduce manual investigation and improve migration planning confidence.
A global telecommunications provider used Selector to model network behavior across control and data planes, accelerating troubleshooting and improving operational visibility at scale.
Absolutely fantastic company. Their approach to intelligent network monitoring and analytics is unique and refreshing. I can’t recommend them highly enough. I honestly get excited by weekly catch-up calls because of the possibilities.
Principal Engineer, Comcast
Before Selector, we lacked the end-to-end visibility needed to see what was happening across our applications, infrastructure, and network. Now we have a consolidated view of all critical data sources allowing us to proactively detect and resolve issues faster to keep our services running and our customers happy.
VP of IT Operations, TracFone
Our goal is to keep service up – always. With Selector, we are constantly monitoring availability and performance. If an abnormal condition arises, we take immediate action.
Senior Manager of Infrastructure & Software Cloud Delivery, Bell
Selector is a next-generation tool which provides comprehensive visibility and automation capabilities to integrate with other platforms and products. This reduces the burden on our operations team, allowing us to improve incident and change management processes as well as detection and identification of network issues.
Digital Infrastructure Company
Selector has significantly enhanced the operations team workflow by improving alert visibility, correlating alerts, and assigning value to them. Also, the implementation of auto-incidents has been pivotal in reducing missed incidents and helping prioritize those that occur most frequently, enabling us to achieve faster response times.
Digital Infrastructure Company
Selector has provided our operations team with valuable insights and analytics. By analyzing vast amounts of data, Selector can identify patterns, anomalies, and trends, enabling operators to make data-driven decisions and optimize their activities. This has led to improved resource allocation, better capacity planning, and enhanced overall performance.
Digital Infrastructure Company
Selector has played a crucial role in automating and streamlining our operations. By leveraging advanced learning algorithms, Selector can proactively detect and resolve incidents, reducing downtime and minimizing the impact on operations. This has resulted in improved system availability and increased productivity.
Digital Infrastructure Company
Selector has revolutionized our operations and greatly enhanced the efficiency of our team. With the implementation of Selector, operators have experienced significant improvements across network monitoring and incident management.
Digital Infrastructure Company
As a next-generation observability tool, Selector AI is designed to work seamlessly across environments and industries, showcasing the transformative power of AI to elevate network resilience, minimize failures, and mitigate human error.
Digital Infrastructure Company
Selector provides proactive isolation event detection within the routing domain by correlating a range of packet loss metrics, automatically alerting the on-call engineer with precise location data and actionable insights to expedite troubleshooting. This intelligent approach has significantly reduced Mean Time to Repair (MTTR), enabling engineers to zero in on critical metrics that directly enhance customer experience.
Digital Infrastructure Company
Manual monitoring relies on engineers spotting alerts before raising incidents. If an engineer fails to notice an alert, there is a high chance the incident will be missed, along with the opportunity to troubleshoot and restore it promptly. Selector correlation ensures that no incidents are missed.
Digital Infrastructure Company
Selector has been a significant advancement in our network monitoring, marking a major milestone in automation. Prior to Selector, the incident KPI target was a challenge for our operations team. However, with Selector’s correlation capabilities, the time taken to address incidents has been significantly reduced compared to manual processes.
Digital Infrastructure Company

Every network engineer carries an instinct that outsiders mistake for caution: a change in one place can travel. Reroute a path, push a policy, drop an interface, and the effect